Too Much Faith in AI's Ability to Refuse
Too Much Faith in AI's Ability to Refuse
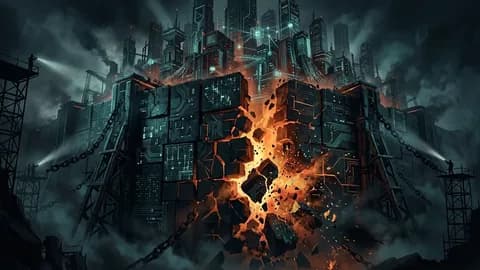
In early large language models, there was no such thing as refusal. A model trained on billions of pages of text developed a broad mastery of violence, vitriol and dangerous knowledge — but no innate sense of "no." Modern models have to be taught to refuse: reward them for turning down dangerous requests, punish them for over-refusing harmless ones. Today, refusal is the load-bearing wall of AI safety. But that wall is built on probabilities, not guarantees.
How Machines Learn to Say No
The 2021 paper "A General Language Assistant as a Laboratory for Alignment" helped popularize the idea that language models should be "helpful, honest, and harmless" (HHH) — including the expectation that, when asked to aid in a dangerous act, the AI should politely refuse.
In practice, early models would "blab on about anything." Teams started by manually collecting refusal examples from red-teamers, feeding those into training sets. Companies now rely on a combination of fine-tuning, automated exercises and layers of guard models to try to enforce refusal boundaries.
The Swiss Cheese Model
Because the boundary between "helpful" and "harmful" isn't clean-cut, companies stack guard layers. Some classifiers block user inputs before they reach the model. Others check model outputs before returning them. A third class uses "probes" to observe the model's internal activations — essentially reading what the model is "thinking" in latent space to decide if it ought to refuse.
Each layer has holes. The industry calls this the "Swiss cheese model": stack enough slices and hopefully nothing slips through. But the holes are real, and they're often exploitable.
def guarded_reply(prompt: str) -> str:
    if input_guard(prompt).blocked:      # Layer 1: pre-input
        return REFUSAL
    draft = model.generate(prompt)
    if output_guard(draft).blocked:      # Layer 2: post-output
        return REFUSAL
    if probe_detect(draft.activations).blocked:  # Layer 3: internal state
        return REFUSAL
    return draft
Each guard is probabilistic. None is infallible — and adding these classifiers is expensive, with some reported to add significant compute costs.
Refusal Is Not Moral Reasoning
We don't fully understand how models decide to refuse. Research suggests refusal behavior corresponds to patterns in the model's activation space — often described as "high-dimensional polyhedral cones." But even that is an approximation. As researchers have found, there are other elements governing refusal beyond those we can easily identify; removing certain activations can stop refusal entirely.
In short: refusal works by statistics, not by conscience. The same prompt can sometimes pass and sometimes be blocked. That makes it unreliable as the single point of failure for high-stakes behavior.
Failure Modes and Jailbreaks
Jailbreaking — getting a model to do what its guardrails forbid — has proven remarkably persistent. From "poetic verse" attacks to "refuse, then comply" tricks, attackers keep finding new paths through the Swiss cheese. As AI agents become more capable of taking external actions (filing forms, sending messages, calling APIs), the consequences of a failed refusal can be irreversible.
Over-Refusal: Collateral Damage
Guardrails can't be made perfectly tight without catching innocent queries. Models have been known to over-refuse harmless requests, from simple questions about fermentation to legitimate research. For researchers trying to use AI for good — from security to medical research — this can be frustrating. But dialing back guardrails risks letting genuinely dangerous outputs slip.
Censorship at Global Scale
The deeper problem: who draws the line? Models are far more likely to refuse to criticize repressive governments than democratic ones. In a Meta Oversight Board study, models were more than twice as likely to refuse to criticize restrictive jurisdictions compared to permissive ones. In some cases, models cited lèse-majesté or local law to justify refusing to criticize certain leaders, while readily doing so for others.
As AI becomes the default way people seek information, the same refusal machinery can be repurposed — deliberately or inadvertently — as a tool of global censorship. When refusal becomes geographically uneven, it's no longer just about blocking bomb-making instructions; it's about exporting speech restrictions at scale.
The Real Trade-Off
The fundamental issue is this: the knowledge that makes AI helpful and potentially lifesaving is inseparable from the knowledge that can be misapplied. You can't surgically remove dangerous capabilities without dulling useful ones. That trade-off is unavoidable.
But placing all of our safety hopes on "the model will say no" is risky. Refusal is necessary — but it's also probabilistic, gameable, and politically malleable. Relying on it as the load-bearing wall means accepting both the inevitability of some catastrophic failures, and the very real risk that refusal will be weaponized to limit speech.
The better we build agents, the more urgent it becomes: constrain what they can do, not just what they say. Allowlists, human approval for irreversible actions, sandboxing, and read-only defaults are far more reliable than hoping a statistical classifier says "no." Because in the real world, "no" doesn't always work — and when it matters most, we shouldn't have to cross our fingers for it.
Sources
- MIT Technology Review: We’re putting too much faith in AI’s ability to say no
- Meta Oversight Board: An Export We Don't Want: How AI Models May Be Globalizing Restrictions On Our Speech
- arXiv: A General Language Assistant as a Laboratory for Alignment
// author
Editor & Operator
Mohd Firdaus Abu Bakar (MrDodgerX) is an enterprise geospatial systems engineer in Malaysia and the editor behind hejes.my. He runs the briefing pipeline, curates and edits every draft, verifies each factual claim against primary sources, and presses the publish button — nothing ships without his review. He writes about AI, security and Malaysia's tech scene from a builder's perspective. Professional profile and code: the links below.
// sources //
fact-check verified · 10 OCT 2026 · hejes-content-fact-check
- We’re putting too much faith in AI’s ability to say noMIT Technology Review · accessed 10 OCT 2026
- An Export We Don't Want: How AI Models May Be Globalizing Restrictions On Our SpeechMeta Oversight Board · accessed 10 OCT 2026
- A General Language Assistant as a Laboratory for AlignmentarXiv · accessed 10 OCT 2026
related //
Claude Mythos: 26K Findings and the Human Triage Bottleneck
Anthropic's Mythos generated 26,153 candidate findings via Project Glasswing, but few reached disclosure. The bottleneck is human triage, not discovery.
Claude Fable 5.1: Smarter Coding, 75% Cheaper Cache Reads
Claude Fable 5.1 doubles down on long agentic work — 52.6% on Terminal-Bench-Science — and cache reads drop 75%. Mythos 5.1: same model, looser guardrails.
Frontier AI Labs Still Lack Rogue Model Containment Plans
A Guidelight audit of five frontier labs finds nobody publishes a full plan for containing a rogue model — and Anthropic, the safety champion, scored zero.
// join the feed
one fresh insight per week. no spam, ever.
weekly digest. unsubscribe anytime.